Measuring or Manufacturing? The Hidden Power of Political Polling in American Elections
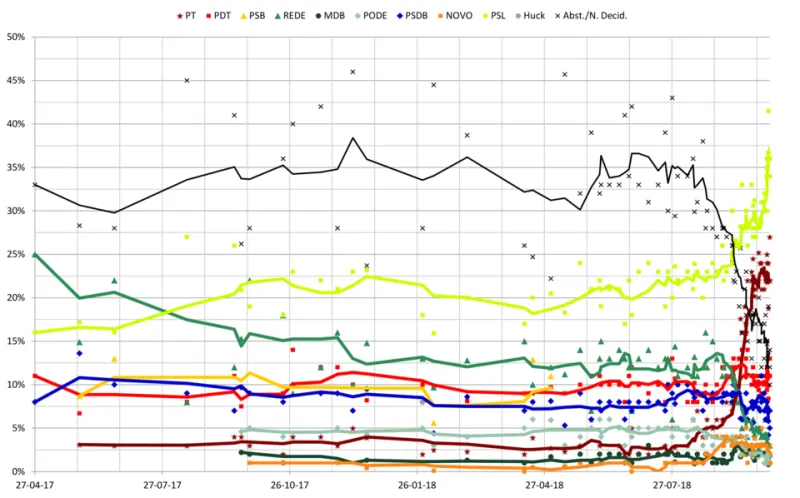
Photo: Denis Rizzoli, CC BY-SA 4.0, via Wikimedia Commons
Every election cycle, polling numbers flood the American news landscape with the authority of hard data. Percentages are cited in headlines, debated on cable panels, and obsessed over by campaign strategists. Yet the firms producing these figures are rarely subjected to the same scrutiny they apply to candidates. Behind the scientific veneer of margin-of-error disclaimers and weighted sampling lies an industry whose choices — about whom to call, whose answers to count, and precisely when to publish — can reshape the electoral landscape as surely as any campaign advertisement.
The Illusion of Objectivity
Polling is frequently described in the language of science: random sampling, statistical significance, confidence intervals. That vocabulary lends an air of impartiality that most political actors could only dream of projecting. But polling is not physics. Every survey involves a cascade of discretionary decisions, each of which quietly tilts the final number.
Consider the question of likely voter screens — the criteria pollsters use to determine whose responses actually count. A firm that defines a "likely voter" as someone who participated in the last three elections will produce a very different electorate than one requiring participation in only one. In a competitive Senate race, that single methodological choice can swing a published result by three to five percentage points. Neither approach is objectively wrong; both reflect assumptions about who will show up in November. But those assumptions are made by human beings working within institutions that have their own financial interests and ideological cultures.
Similarly, the order and phrasing of questions shape responses in ways that are well-documented in academic literature but rarely disclosed to the public consuming the final headline number. A poll that asks respondents about crime before asking them to evaluate a candidate's job performance will frequently produce different approval ratings than one that reverses the sequence. These are not rounding errors. They are structural features of the instrument itself.
The Conflict-of-Interest Architecture
The deeper problem is not that any single methodological choice is fraudulent. It is that the firms making these choices are embedded in a web of financial relationships that creates systematic pressure to produce results favorable to paying clients.
Several of the most prominent polling organizations in the country operate simultaneously in at least three distinct markets: they conduct internal polling for campaigns, they sell data subscriptions or branded surveys to media outlets, and they accept contracts from advocacy organizations and super PACs seeking to advance specific policy agendas. Each of these clients has an interest in seeing particular numbers published. Each relationship, individually, may be disclosed in fine print. Collectively, they constitute a conflict-of-interest architecture that the industry has never been compelled to meaningfully address.
When a firm is simultaneously paid by a Senate campaign, contracted by a regional television network to produce publicly released surveys, and retained by an outside group supporting the same candidate's policy positions, the independence of its public-facing work becomes a legitimate question. Disclosure requirements in this space remain largely voluntary, and the American Association for Public Opinion Research — the closest thing the industry has to a self-regulatory body — lacks meaningful enforcement power.
The Self-Fulfilling Prophecy Problem
Perhaps the most consequential dynamic in contemporary political polling is the way published numbers construct the very reality they purport to describe. This is not a fringe critique. It is a recognized phenomenon with direct implications for democratic competition.
Candidates polling below a certain threshold — typically ten percent in a primary field, or outside the margin in a general election — face a predictable cascade of consequences. Major media organizations use polling averages to determine debate eligibility, effectively ending campaigns before voters in most states have cast a single ballot. Donors, who follow polling as closely as any political professional, redirect contributions toward candidates who appear viable. Journalists assign fewer reporters, produce fewer stories, and schedule fewer interviews with candidates who the polls suggest are losing. The result is that a polling deficit, however it originated, tends to compound itself through mechanisms entirely external to the candidate's actual message or qualifications.
In the 2020 Democratic presidential primary, several candidates with substantial policy platforms and meaningful grassroots support were excluded from debate stages based on polling thresholds that their campaigns argued were being measured inconsistently across different firms. Whether or not those complaints were entirely justified, the structural dynamic they identified was real: polling numbers had become gatekeeping instruments, and the firms producing those numbers had acquired a form of veto power over the composition of the candidate field that no electorate ever explicitly granted them.
Strategic Timing as a Political Tool
Beyond methodology and conflicts of interest, the timing of poll releases deserves far greater scrutiny than it currently receives. Surveys are not published the moment they are completed. They move through editorial and strategic review processes before reaching the public. The decision about when — and whether — to release a particular set of findings is itself a consequential editorial act.
Campaign-affiliated pollsters have an obvious incentive to publish favorable internal numbers at moments designed to generate momentum and donor confidence, and to quietly shelve surveys that tell a less encouraging story. But even ostensibly independent media polls are subject to timing pressures. A network sitting on a survey showing an unexpected surge for a trailing candidate may rush publication to drive traffic during a news lull, or hold it pending a scheduled interview that the numbers would make more newsworthy. Neither decision is inherently corrupt, but both illustrate that the publication of polling data is an editorial act with political consequences, not a neutral transmission of objective information.
Toward Greater Accountability
None of this is an argument that polling is without value. Aggregated survey data, when produced by methodologically rigorous firms and interpreted with appropriate humility, remains one of the more useful tools available for understanding public opinion at scale. The problem is not polling itself. It is the uncritical deference the political press and the broader public extend to polling as though it were a category of knowledge immune to the incentives and biases that distort every other form of political information.
A more accountable polling ecosystem would require, at minimum, mandatory disclosure of all client relationships for any firm releasing publicly cited surveys, standardized reporting of methodological choices including likely voter screens and question sequencing, and a serious reckoning with the debate-eligibility and media-coverage thresholds that allow polling numbers to function as candidate eliminators.
Until those reforms materialize, voters and political observers would be well-served by treating every published poll not as a measurement of where an election stands, but as an artifact produced by an institution with its own interests, assumptions, and relationships — one whose numbers may be shaping the race as much as they are reflecting it.
The pollsters will tell you they are simply reading the room. It is worth asking who furnished it.